EZENRUI ZHANG

STRATEGY / RESEARCH / ANALYTICS

张恩瑞Enrui Zhang

Enrui Zhang张恩瑞

佐治亚理工学院Georgia Institute of Technology

理学硕士 · 管理科学与工程MSc Management (Master of Science)

印第安纳波利斯大学University of Indianapolis

理学学士 · 工商管理Bachelor of Science · Business Administration and Management

浏览项目Explore my work ↗zhangenrui11@outlook.com
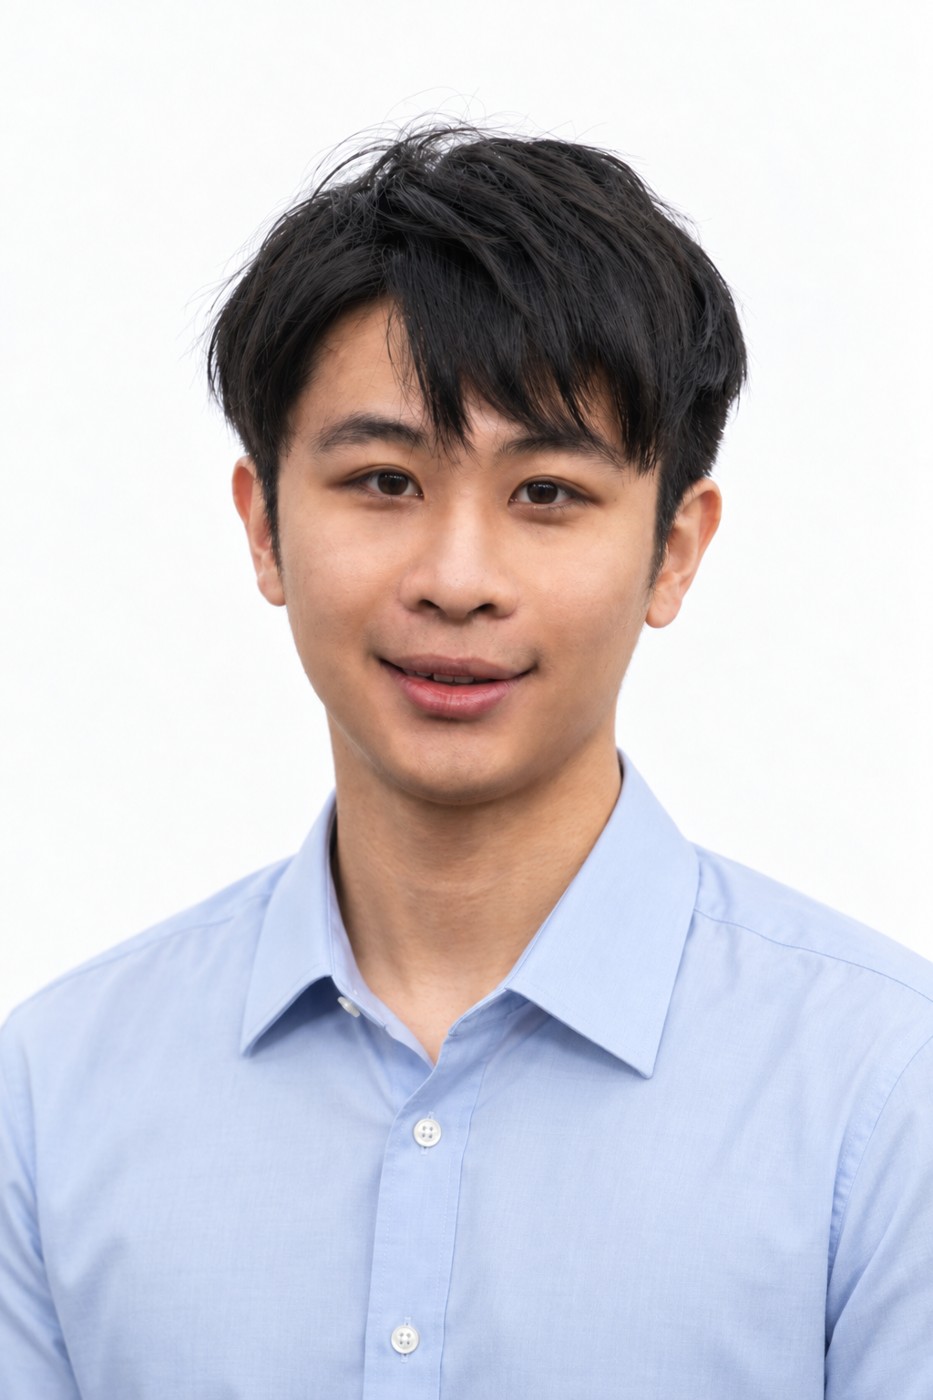
Enrui Zhang wearing a light blue shirt
ENRUI ZHANG张恩瑞

SELECTED PROJECTS

从问题出发,走向发现。Questions, methods, discoveries.

行业研究 · 咨询策略 · AI 应用 · 因果分析Industry research · Consulting · Applied AI · Causal analysis

01

INDUSTRY RESEARCH

具身智能:数据如何成为商业机会?Embodied AI: when does data become a business?

机器人需要更多数据,但“更多”本身并不等于更好的训练,更不等于可持续的商业模式。Robots need more data. But more data does not automatically mean better learning—or a sustainable business model.

研究背景The question

具身智能将 AI 从数字世界带入物理世界,也让数据问题变得更复杂:动作需要与感知对齐,任务与环境不断变化,失败和恢复过程同样重要。本研究关注机器人数据从哪里来、如何生产,以及第三方供应商能在哪些环节创造价值。Embodied AI brings learning into the physical world, where actions must align with perception, tasks and environments vary, and failures and recovery matter. This study asks where robotics data comes from, how it is produced, and where third-party suppliers can create value.

分析框架Research approach

以真实世界采集、遥操作、自主 rollout、仿真与合成数据、人类视频及公开数据集为供给地图,结合技术文献、公司与融资资料、专家访谈,连接技术需求、生产经济性、Build / Buy / Partner 决策和商业化路径。The supply map covers real-world collection, teleoperation, autonomous rollouts, simulation and synthetic data, human video, and public datasets. Technical literature, company and financing evidence, and expert interviews connect training needs with production economics, Build / Buy / Partner choices, and commercialization.

发现一:稀缺的是可训练经验Finding 1: usable experience is scarce

原始轨迹数量只是起点。任务相关性、动作与时间对齐、环境覆盖和失败恢复信息,决定了数据能否成为有效训练经验。评估生产成本也应追踪“计划采集 → 实际采集 → 可用数据”的漏斗,而不能只比较操作员工资。Raw trajectory counts are only a starting point. Task relevance, action and temporal alignment, environmental coverage, and failure-recovery context determine training usefulness. Production economics should follow scheduled collection through to usable output, rather than compare operator wages alone.

发现二:工具与质量环节更值得关注Finding 2: infrastructure and quality matter

相比标准化的原始轨迹交易市场,数据基础设施、质量保证和专业化生产瓶颈呈现出更强的结构性机会。但部署反馈不自动构成商业飞轮;数据权利、续约、客户回报和跨客户复用仍是需要验证的条件。Data infrastructure, quality assurance and specialized production bottlenecks present a stronger structural opportunity than standardized raw-trajectory marketplaces. Deployment feedback alone is not a commercial flywheel: data rights, renewals, customer returns and cross-customer reuse still require validation.

结论如何使用Using the findings

这份 65 页报告提供的是有证据边界的行业判断:仿真更像放大层,而非真实数据的普适替代;大数据集或大机群也不自动构成护城河。机会评估应落到具体任务、工作流嵌入和可持续的商业验证。The 65-page report offers evidence-bounded industry judgments. Simulation acts as an amplification layer, not a universal replacement for real-world data; large datasets or fleets do not automatically create moats. Opportunities should be evaluated against specific tasks, workflow integration and durable commercial evidence.
阅读报告原件 · 65 页 PDFRead the original report · 65-page PDF

若预览未显示,请在新窗口打开。报告原件为中文。If the preview does not appear, open it in a new window. The original report is in Chinese.

02

Consulting/GTM Strategy

让远程睡眠服务找到合适的患者Finding the right patients for virtual sleep care

服务能力已经具备,真正的增长问题是:先服务谁,用什么价值主张触达,以及如何判断获客是否有效?The service infrastructure was in place. The growth challenge was who to prioritize, which value proposition to communicate, and how to measure acquisition.

项目背景与 GTM 问题Context & go-to-market challenge

亚特兰大一家专科医疗机构计划推出 Virtual Lifestyle & Sleep Program。项目围绕既有远程医疗基础设施,构建目标患者细分、定位、信息传递与获客策略,并将营销需求与临床服务容量相匹配。An Atlanta specialty clinic planned a Virtual Lifestyle & Sleep Program. Building on existing telehealth infrastructure, the engagement developed patient segmentation, positioning, messaging and acquisition strategy, aligning demand generation with clinical capacity.

Segments:按需求而非年龄划分Segments: needs before demographics

两类核心画像对应不同的需求:卡车司机与轮班工作者关注疲劳、安全和时间弹性;合并慢性病的患者更关注睡眠与整体健康管理的衔接。框架由 Segment → Need State → Value Proposition → Message → Channel 串联。Two core archetypes imply different needs. Truck drivers and shift workers prioritize fatigue, safety and scheduling flexibility; patients with chronic comorbidities seek sleep care integrated with broader health management. The framework links Segment → Need State → Value Proposition → Message → Channel.

渠道与试点设计Channels & pilot design

按细分客群匹配雇主或车队合作、医生转介、搜索与本地 SEO、患者教育等渠道。六个月试点方案采用 test-and-learn 逻辑,将渠道、受众、CTA、预算和继续/暂停规则连接起来,而非先扩大投放再评估。Match segments with employer or fleet partnerships, provider referrals, search and local SEO, and patient education. A proposed six-month test-and-learn pilot connects channel, audience, CTA, budget and continue/pause rules before scaling acquisition.

KPI measurementKPI measurement

衡量链条从 qualified leads 到 completed enrollments,跟踪每条合格线索成本、线索至入组转化率、各来源转介量和落地页转化率。盈亏平衡框架连接营销支出与新增患者净贡献;在支付方结构、人员成本和真实转化数据不足时,不将 ROI 假设包装成已实现成果。Track the funnel from qualified leads to completed enrollments using cost per qualified lead, lead-to-enrollment conversion, referrals by source and landing-page conversion. A break-even framework connects marketing spend with net contribution per new patient; ROI remains assumption-driven until payer mix, staffing costs and conversion evidence are available.

03

SKILLS / APPLIED AI / OPEN SOURCE

把一次研究,整理成可复用的 Agent SkillFrom a research process to a reusable agent skill

Industry Research Skill 将行业研究中的工作方法转化为可执行的 AI 工作流,让研究过程可追踪、可审查、可接续。Industry Research Skill turns research practices into an AI workflow designed to make work traceable, reviewable and resumable.

为什么做 SkillsWhy a skill?

长周期研究容易遇到来源分散、证据冲突和跨会话状态丢失。项目源于具身机器人数据市场研究的实际工作流:将证据搜集与判断等关键环节整理为可复用规则,而不是每次重新写一段研究提示词。Long research projects face scattered sources, conflicting evidence and lost context between sessions. Drawing on the robotics data-market research process, this project packages evidence collection and judgment into reusable rules instead of restarting with a new research prompt each time.

工作流如何组织How the workflow works

证据追踪记录来源、口径、期间、单位与主张依据;阶段审查保留冲突、假设和未知;跨会话接续保存范围、审查决定、产物位置与接续索引。精简和完整两种模式适配不同研究复杂度。Evidence tracking records sources, definitions, periods, units and claim support. Stage reviews retain conflicts, assumptions and unknowns. Session handoffs preserve scope, review decisions, artifact locations and a resumption index. Lightweight and full modes support different research complexity.

从方法到 AI 应用From method to applied AI

公开项目包含一个主 Skill、四份参考文件与六份按需模板,并提供中英文说明。它展示的是将领域方法转译为 AI 可执行流程的应用思路:人定义目标与判断边界,AI 辅助生成文件并执行组织化任务。The public project includes one main skill, four reference files and six on-demand templates, with Chinese and English documentation. It translates domain methods into an AI workflow: people define goals and judgment boundaries, while AI assists with file generation and structured tasks.

实验带来的反思What validation revealed

公开文档披露,三组历史配对未观察到核心质量评分提升,产物更大、自报耗时更长。因此,当前价值主张聚焦研究过程的组织与可追溯性;质量提升和成本优势仍需进一步验证。Public documentation reports no observed core-quality score improvement across three historical paired comparisons, alongside larger artifacts and longer self-reported time. The current proposition centers on organization and traceability; quality and cost advantages require further validation.

04

NSW / CAUSAL INFERENCE / AI EXPERIMENT

均值接近,是否代表 AI 理解了现实?A close average. A faithful model of reality?

以职业培训对收入的影响为起点,进一步检验:LLM 能否构造可信的“如果没有参加培训”的反事实?Starting with the earnings effect of job training, the project asks whether an LLM can construct a credible “without training” counterfactual.

研究背景Research context

NSW(National Supported Work)是美国一项帮助就业困难群体重返劳动力市场的就业援助示范项目,通过提供有支持和督导的临时工作经历,研究就业支持是否能改善后续收入。本研究使用的 LaLonde / NSW 数据包含 445 人,其中 185 人接受培训、260 人属于随机对照组。真实实验对照既支持培训效果分析,也为检验 AI 生成的反事实提供了难得的基准。 数据背景 ↗The National Supported Work (NSW) demonstration was a U.S. employment-support program for people facing persistent barriers to work. It offered temporary jobs with support and supervision to examine whether work experience improved later earnings. The LaLonde / NSW sample used here contains 445 people: 185 training participants and 260 randomized controls. The experimental control supports treatment-effect analysis and provides a rare benchmark for testing AI-generated counterfactuals. Dataset background ↗

方法论Methodology

结合实验均值比较、回归、年龄与教育异质性检验,以及以 1975 年和 1978 年收入构造的双重差分。另隐藏受训者的真实后期收入,只使用培训前特征,让 LLM 生成反事实收入,并比较均值、离散程度和零收入群体。Combine experimental mean comparisons, regression, age and education heterogeneity tests, and Difference-in-Differences using 1975 and 1978 earnings. In a separate experiment, hide treated participants’ observed outcomes and generate counterfactual earnings from pre-treatment characteristics, comparing means, dispersion and zero-earner coverage.

发现:平均效果与分布是两回事Finding: averages and distributions differ

简单实验收入差约为 $1,794,受控 DiD 估计约为 $1,529(p≈0.023)。LLM 推导的 ATE 与实验基准只差约 3.5%,但收入分布的标准差低约 39%,且没有预测出任何零收入者。均值看似准确,现实中的关键尾部却消失了。The simple experimental earnings difference was about $1,794; controlled DiD estimated about $1,529 (p≈0.023). The LLM-implied ATE differed from the experimental benchmark by only about 3.5%, yet the earnings distribution’s standard deviation was roughly 39% lower, with no predicted zero earners. A plausible mean concealed missing tails.

这意味着什么Why it matters

用于决策的模型不能只通过平均 KPI 验收。LLM 反事实可帮助探索和敏感性分析,但本实验不支持它替代实验或准实验识别。同样,教育异质性检验未显著,也不能把点估计差异直接变成定向政策。Decision models should not be validated on an average KPI alone. LLM counterfactuals can support exploration and sensitivity analysis, but this experiment does not justify replacing experimental or quasi-experimental identification. Likewise, a non-significant education interaction does not justify a targeting policy from point estimates alone.

05

CRITEO / UPLIFT MODELING

数据粒度约束下的广告定向Advertising Targeting Under Data Granularity Constraints

值得投放的人,不一定是最可能购买的人,而可能是那些会因为广告改变行为的人。The best person to target is not necessarily the most likely buyer, but someone whose behavior the advertisement can change.

背景与决策问题Context & decision

Criteo Uplift 数据来自广告技术公司 Criteo 发布的真实随机广告实验:一部分用户被随机排除在广告定向之外,数据记录广告分组、匿名用户特征,以及后续的网站访问和转化。这让我们可以比较“允许投放”与“不投放”的结果,识别广告真正带来的增量响应。当用户级数据变得更粗粒度,这种识别还能保持有效吗?这项团队研究使用 Criteo 随机广告实验,以网站访问为主要结果,比较选择性投放与全量投放,并检验数据退化对策略表现的影响。 数据背景 ↗The Criteo Uplift dataset comes from real randomized advertising experiments released by advertising technology company Criteo. A randomly selected holdout group was excluded from ad targeting; the records contain assignment, anonymized user features, and subsequent visits and conversions. This makes it possible to compare targeting eligibility with no targeting and estimate incremental response. Can that response still be identified as user data become less granular? This team study uses Criteo randomized advertising data, with website visits as the primary outcome, to compare selective and blanket advertising and test policy performance under degraded data. Dataset background ↗

方法:从 CATE 到策略评估Method: CATE to policy evaluation

抽取 50 万条观测,按 30 万训练、20 万测试划分。带处理交互项的 Logistic Regression 结合 AIC/BIC 估计条件平均处理效应(CATE),通过阈值生成投放策略,再用 IPW 在留出样本上评估;特征粗化与高斯噪声实验检验策略稳健性。Sample 500,000 observations into 300,000 training and 200,000 test records. Logistic regression with treatment interactions and AIC/BIC selection estimates conditional average treatment effects (CATE). Threshold rules define targeting policies, evaluated with IPW on held-out data; coarsening and Gaussian noise experiments stress-test robustness.

发现:平均效应掩盖了机会Finding: averages hide targeting opportunities

整体广告效应约为 +0.9 个百分点,但 f0 的第二分位组约为 +3.6 个百分点。CATE 定向策略的估计 policy value 约为 0.0475,高于全量投放的 0.0465。差距不大,却说明增量响应与“对所有人投放”并不是同一个优化问题。The overall advertising effect was about +0.9 percentage points, versus about +3.6 points in the second f0 quantile group. Estimated policy value was about 0.0475 for CATE-based targeting and 0.0465 for blanket treatment. The modest gap illustrates that incremental-response targeting is a different optimization problem from advertising to everyone.

发现:保留结构可能比单纯降噪更重要Finding: preserving structure matters

在本项目的模拟退化框架中,特征粗化整体比高斯噪声更影响定向表现;高价值客群也在特征空间中呈局部聚集。这提示数据策略需要关注分辨率与结构信息,但不能据此推广为所有隐私机制的普遍结论。Within this simulated degradation framework, coarsening generally affected targeting more than Gaussian noise; high-value groups also clustered locally in feature space. Data strategy should consider resolution and structural information, without generalizing this result to all privacy mechanisms.

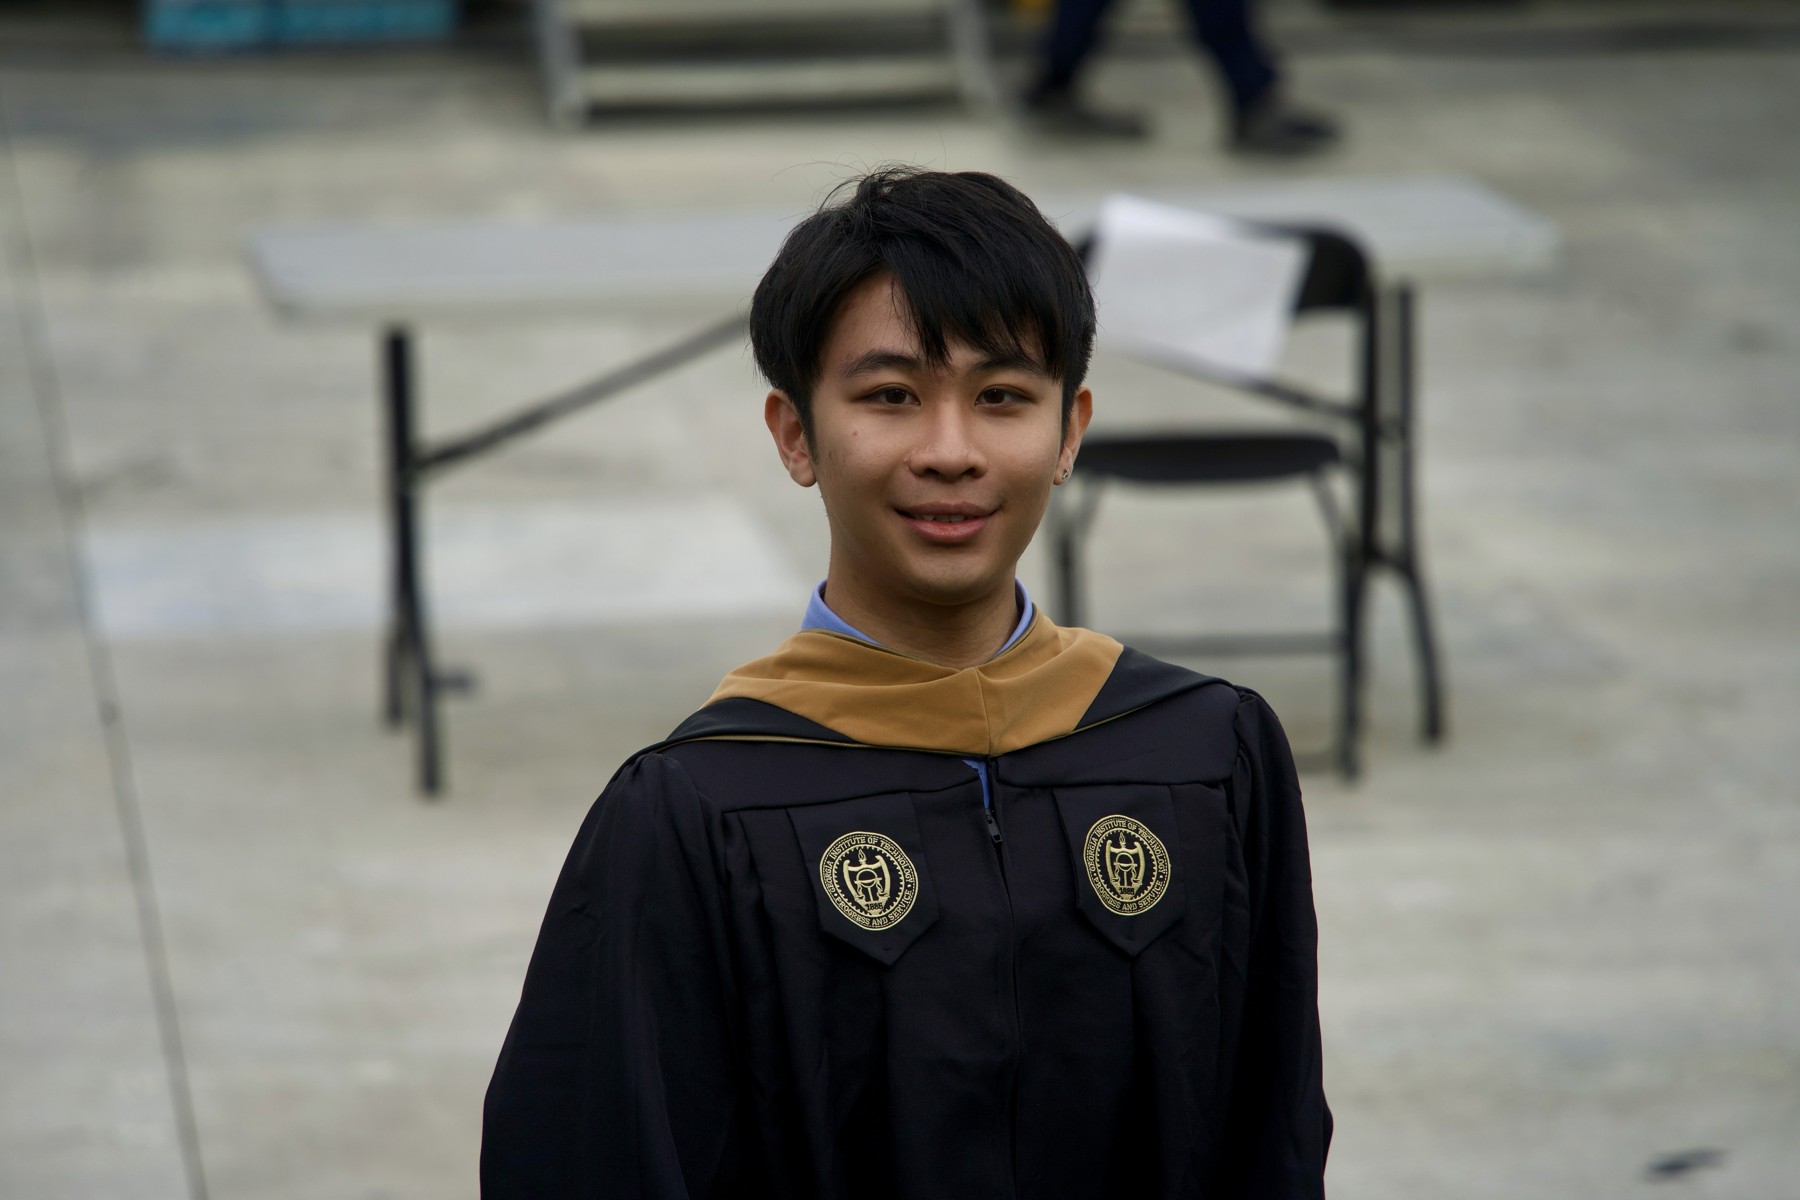
Enrui Zhang in Georgia Tech graduation regalia
GEORGIA TECH · CLASS OF 2026

BEYOND THE RESUME

保持好奇,
走进新的领域。
Stay curious.
Explore new territory.

最令人兴奋的一部分,是走进一个完全陌生的领域,然后迅速弄懂它。The most exciting part is stepping into a completely unfamiliar field—and quickly making sense of it.

从中国到美国;从医疗咨询、冷链物流和工业制造,到消费零售、数字广告,再到 AI 与机器人研究——每一次切换,我都要重新学会一套行业语言、商业逻辑和判断标准。From China to the United States; from healthcare consulting, cold-chain logistics and industrial manufacturing to consumer retail, digital advertising, and AI and robotics research—each transition means learning a new industry language, business logic and set of judgment criteria.

但我真正积累下来的,不是对每个行业的浅尝辄止,而是同一种能力:快速建立认知,把纷杂的信息结构化,找到关键问题,再形成清晰的判断。What I have accumulated is more than a passing familiarity with different industries. It is a consistent ability: to build understanding quickly, structure messy information, identify the key questions and form clear judgments.

这也是我想带进工作的:不只理解问题本身,也理解问题背后的业务、人与情境。That is what I want to bring to my work: understanding not only the problem itself, but also the business, people and context behind it.

WHAT’S NEXT

让研究与分析,
参与真实的商业决策。
Bringing research and analysis
to real business decisions.

关注咨询与战略、行业与投资研究、商业与数据分析方向的机会。Exploring opportunities in consulting & strategy, industry & investment research, and business & data analytics.

zhangenrui11@outlook.com ↗